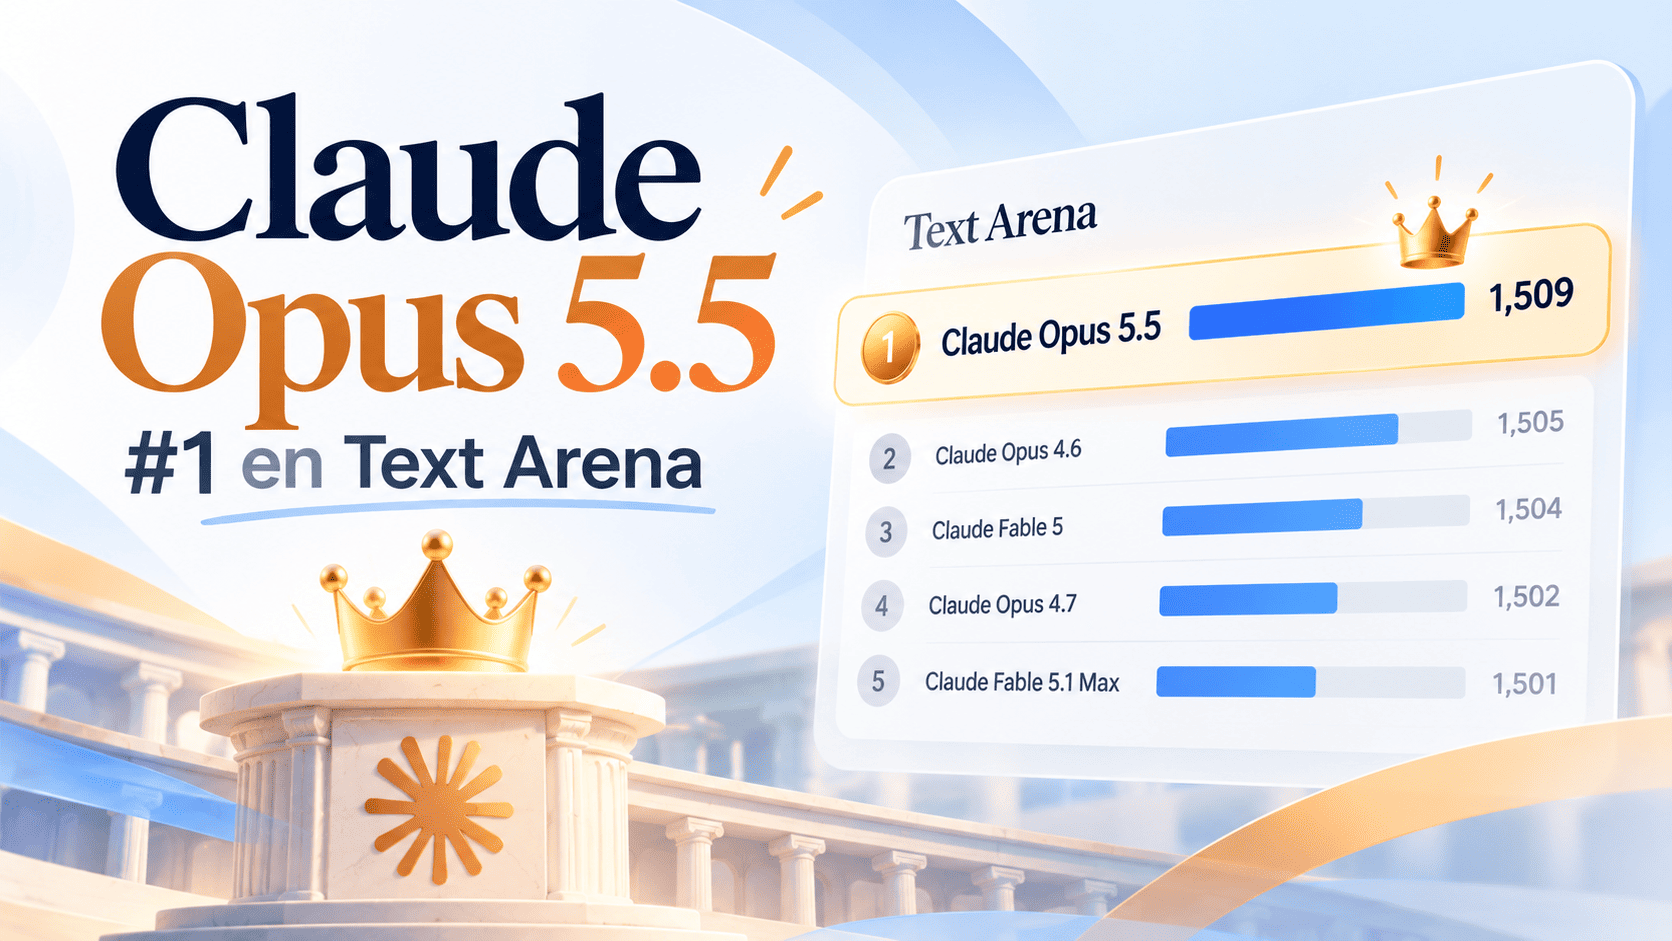
Reviewed September 27, 2026. The September 25 Text Arena snapshot lists Opus 5.5 High at 1509 ±12, 2,307 votes and rank spread 1–10. Rankings change over time.
The headline is confirmed: Claude Opus 5.5 High is first in the reviewed Text Arena snapshot. A leaderboard can help shortlist models, but a business must still check languages, documents, tool calls and decisions affecting its customers.
What does the 1509-point result show?
The September 25 table lists Opus 5.5 High at 1509 ±12 with 2,307 votes. Opus 4.6 High follows at 1505 ±3. Opus 5 High has 1491: an 18-point difference in that snapshot.
These are relative scores, not percentages of correct answers. The uncertainty intervals overlap and the new entry has fewer votes. A four-point gap does not prove superiority on every task.
Arena measures human preference
Arena compares model responses using human choices. Its methodology explains statistical ranking and uncertainty; the table shows score uncertainty and a rank spread. The reviewed spread for Opus 5.5 High is 1–10.
Read the category and adjustments as well as the position. Text comparisons, coding benchmarks and agents using tools ask different questions. Use evidence for the question it actually measures.
Presentation can influence preference
Arena’s style-control research studies answer length and Markdown formatting. It reports ranking changes after controlling for these effects. How an answer is presented can influence its preference alongside its substance.
Separate readability from accuracy in your evaluation. Mark unsupported claims, missing requirements and unusable instructions before rating how convincing an answer sounds.
The release and leaderboard are separate sources
Anthropic announced Opus 5.5 on September 22, 2026. Its release describes availability and improvements across coding, computer use and other work. These are vendor statements; Arena uses a different methodology.
Record the exact model and reasoning setting. This article discusses the “Opus 5.5 High” leaderboard entry, not identical settings or results in every product using the model.
Evaluate your actual business workflow
Prepare representative tasks: English and Spanish enquiries, an incomplete request, extraction from a document and a case where asking a question is correct. Use synthetic or appropriately protected data.
Define success first. A CRM classifier may need valid fields and conservative escalation. Coding needs reviewed changes that satisfy project checks. A support draft needs accuracy in the customer’s language.
- Exact model, settings and prompt version.
- Correctness and missing information.
- Language quality and instruction following.
- Latency, cost and retry behaviour.
- Human escalation and recovery.
Move from a shortlist to a reliable automation
Compare complete outcomes and operating cost after narrowing the candidates. Start with a low-impact step, such as preparing a draft for review, before allowing a model to take customer-facing actions.
In Make or n8n, the model is one part of the process. Validate its output, preserve lead context, define retries and assign exceptions to a person. Value comes from a reliable full workflow, not a number-one badge.
Frequently asked questions
Does 1509 mean 95% accuracy?
No. It is a relative ranking score, not an accuracy percentage for your task.
Is the first position permanent?
No. This article gives a dated snapshot and uncertainty. Votes, filters and new models can change the table.
Should all automations switch to Opus 5.5?
A ranking alone does not justify switching. Compare representative tasks, cost, latency and failure handling first.
Sources & editorial review
Primary sources consulted for this article. Practical recommendations are Meuveryone’s editorial analysis. We do not claim affiliation with these companies.
Use Arena to shortlist models and ask better questions. Choose after evaluating the workflow your business will actually run.
Explore the related service ↗